你在 Table 建立的 Index 真的有效嗎?用範例帶你理解 Coverage Index 的意義

林鼎淵
閱讀約 2 分鐘
這篇文章寫於 2021 年,文中的工具與版本可能已經更新,實作時請以官方文件為準。
本文目錄
我們會在 Table 中建立 Index 以增加搜尋的效率,但建立 Index 的同時也會影響到資料 insert、update、delete 的效率;所以我們在建立 Index 時需要抱持謹慎的態度,這篇文章將帶大家了解 Coverage Index (覆蓋索引)的意義。
SETP 1:建立測試用的 tmp_user Table
- id 為 primary key
- name 為 index
create table tmp_user (
    id bigint(20) not null auto_increment ,
    name varchar(255) not null,
    password varchar(255) ,
    index index_name (name),
    primary key (id))
    engine=innodb
    default character set=utf8 collate=utf8_general_ci;

insert into tmp_user (name, password) values ("寶寶不說","123");
原始碼:init_user.sql(GitHub Gist)
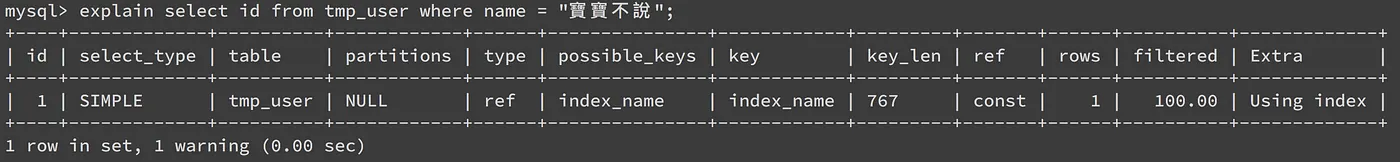
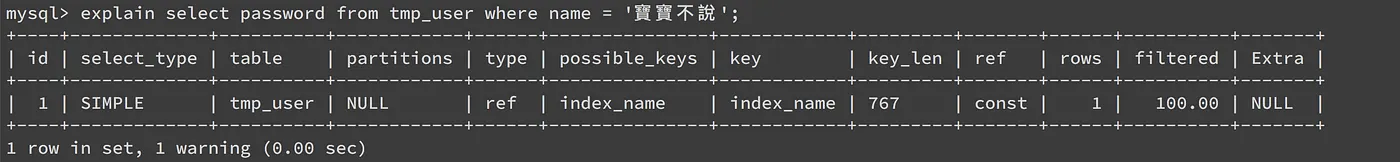
SETP 2:下 SQL 指令了解是否使用 Index
觀察最後「Extra」欄位的資訊
➤ SQL A:
select id from user_table where name= '寶寶不說'
➤ SQL B:
select password from user_table where name= '寶寶不說'
SETP 3:分析 SQL 指令邏輯
➤ SQL A 分析:
select id from user_table where name= '寶寶不說'
因為 name 有建立 index,所以在查詢到 name後可以直接與 id 對應返回結果;因為 name 已經覆蓋了查詢資料的需求,所以稱為 「Coverage Index」
➤ SQL B 分析:
select password from user_table where name= '寶寶不說'
透過 name找到「寶寶不說」對應的 id,接著透過 id這個 primary key 在 Table 重新輪詢才能取得這一列的完整資料。
SETP 4:建立 Coverage Index 優化 SQL B
➤ 先將資料庫 drop 掉
drop table tmp_user;
➤ 重新建立測試資料以及「Coverage Index」
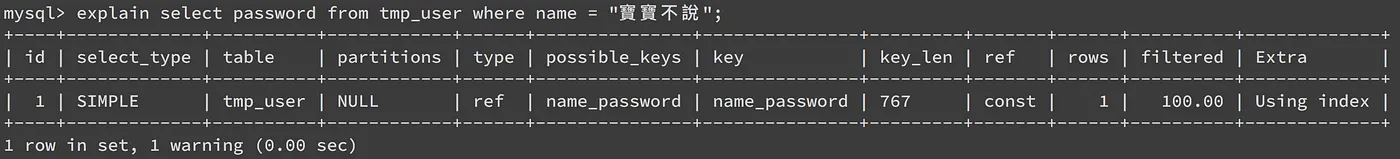
為了避免用 primary key 再次從 Table 查詢的耗能,我們可以把 select 與 where 用到的欄位(name、password)做聯合索引,這樣就能夠直接使用索引查詢而不需用 primary key 重新比對,這就是「Coverage Index」的應用。
create table tmp_user (
   id bigint(20) not null auto_increment ,
   name varchar(255) not null,
   password varchar(255) ,
   primary key (id))
   engine=innodb
   default character set=utf8 collate=utf8_general_ci;

insert into tmp_user (name, password) values ("寶寶不說","123");

alter table tmp_user add index name_password(name,password);
原始碼:coverage_example.sql(GitHub Gist)
➤ 再次執行 SQL B:
explain select password from tmp_user where name = '寶寶不說';
你會發現本次的查詢就有使用到「Index」嚕~
總結
- Index 需要根據實際情境建立
- 如果查詢會用到多個欄位,建立 Coverage Index 來優化查詢效率
- 如果資料高達百萬筆,你的 Index 是否有效是非常重要的事情


留言載入中…